
I am an MPhil (master by research) student at The University of Hong Kong, supervised by Prof. Hongyang Du at NICE Lab. Prior to this, I earned my Bachelor's degree at the National University of Singapore, where I completed my capstone under the supervision of Prof. Bingsheng He. My research interests include Data Agents, LLM Evaluation, Multimodal Models, and Efficient AI. I am open to collaborating with people who share similar research interests.
I am currently seeking PhD opportunities for Fall 2027. Please feel free to reach out if you see a potential research fit.
Education and Awards
-
 The University of Hong KongSep. 2025 - PresentElectrical and Computer EngineeringMaster of Philosophy
-
 National University of SingaporeAug. 2021 - Jul. 2025Computer ScienceBachelor of Computing (Honours), Minor: Economics
-
 Huazhong University of Science and TechnologySep. 2020 - Jul. 2021Artificial Intelligence (dropped out)
-
Dean's ListNUS SEM2 24-25
-
Top Student for CS Research MethodologyNUS SEM1 24-25
Intern Experience
-
LUKA Lab, UCDJun. 2026 - Oct. 2026Supervisor: Muhao Chen, Mentor: Tenghao Huang
-
DIAL Lab, HKUST (GZ)Jul. 2025 - Oct. 2025Supervisor: Yuyu Luo
-
Activate Interactive Pte Ltd, SingaporeJan. 2024 - Jun. 2024Government Solutions Department for Ministry of Manpower
-
X AI Lab, PolyU HKSep. 2023 - Jan. 2024Supervisor: Xiao Huang
-
HPC-AI Lab, NUSAug. 2022 - Nov. 2023Supervisor: Yang You
News
Selected Publications (view all )
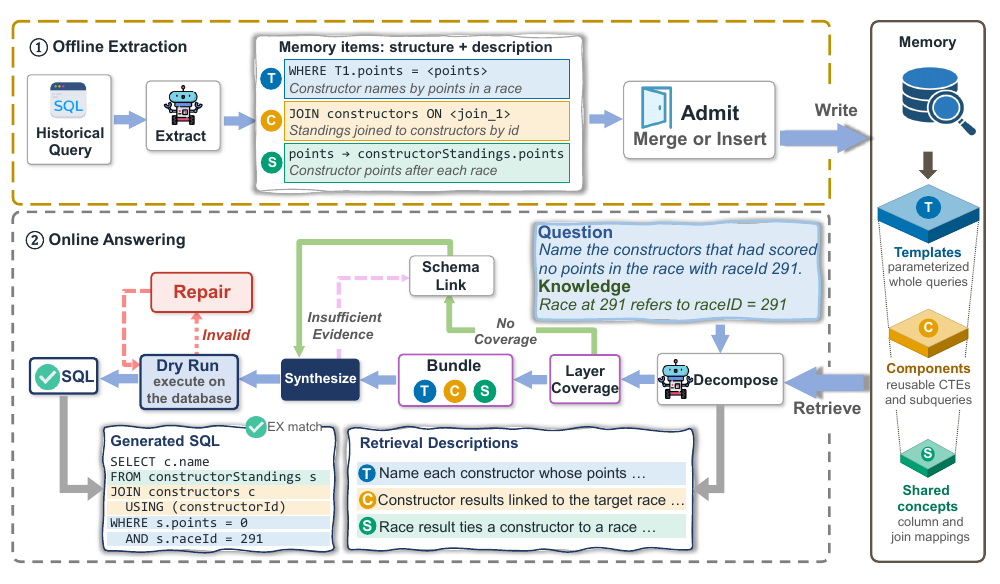
MEM-SQL: Memory-Empowered Text-to-SQL
Xiaoqi Wang*, Wenqi Pei*‡, Shizheng Hou*, Yilai Liu, Han Chen, Boyan Li, Yuyu Luo, Hongyang Du (* equal contribution, ‡ project lead)
Preprint 2026
We introduce MEM-SQL, which reuses verified query templates, SQL components, and schema mappings from query history and consults the database schema when memory provides insufficient evidence. On HARE, our benchmark for historical SQL reuse, MEM-SQL raised mean execution accuracy from 37.1% to 50.0% across six language models while reducing input tokens by 76.6% and latency by 68.8% on average relative to direct generation without history.
MEM-SQL: Memory-Empowered Text-to-SQL
Xiaoqi Wang*, Wenqi Pei*‡, Shizheng Hou*, Yilai Liu, Han Chen, Boyan Li, Yuyu Luo, Hongyang Du (* equal contribution, ‡ project lead)
Preprint 2026
We introduce MEM-SQL, which reuses verified query templates, SQL components, and schema mappings from query history and consults the database schema when memory provides insufficient evidence. On HARE, our benchmark for historical SQL reuse, MEM-SQL raised mean execution accuracy from 37.1% to 50.0% across six language models while reducing input tokens by 76.6% and latency by 68.8% on average relative to direct generation without history.
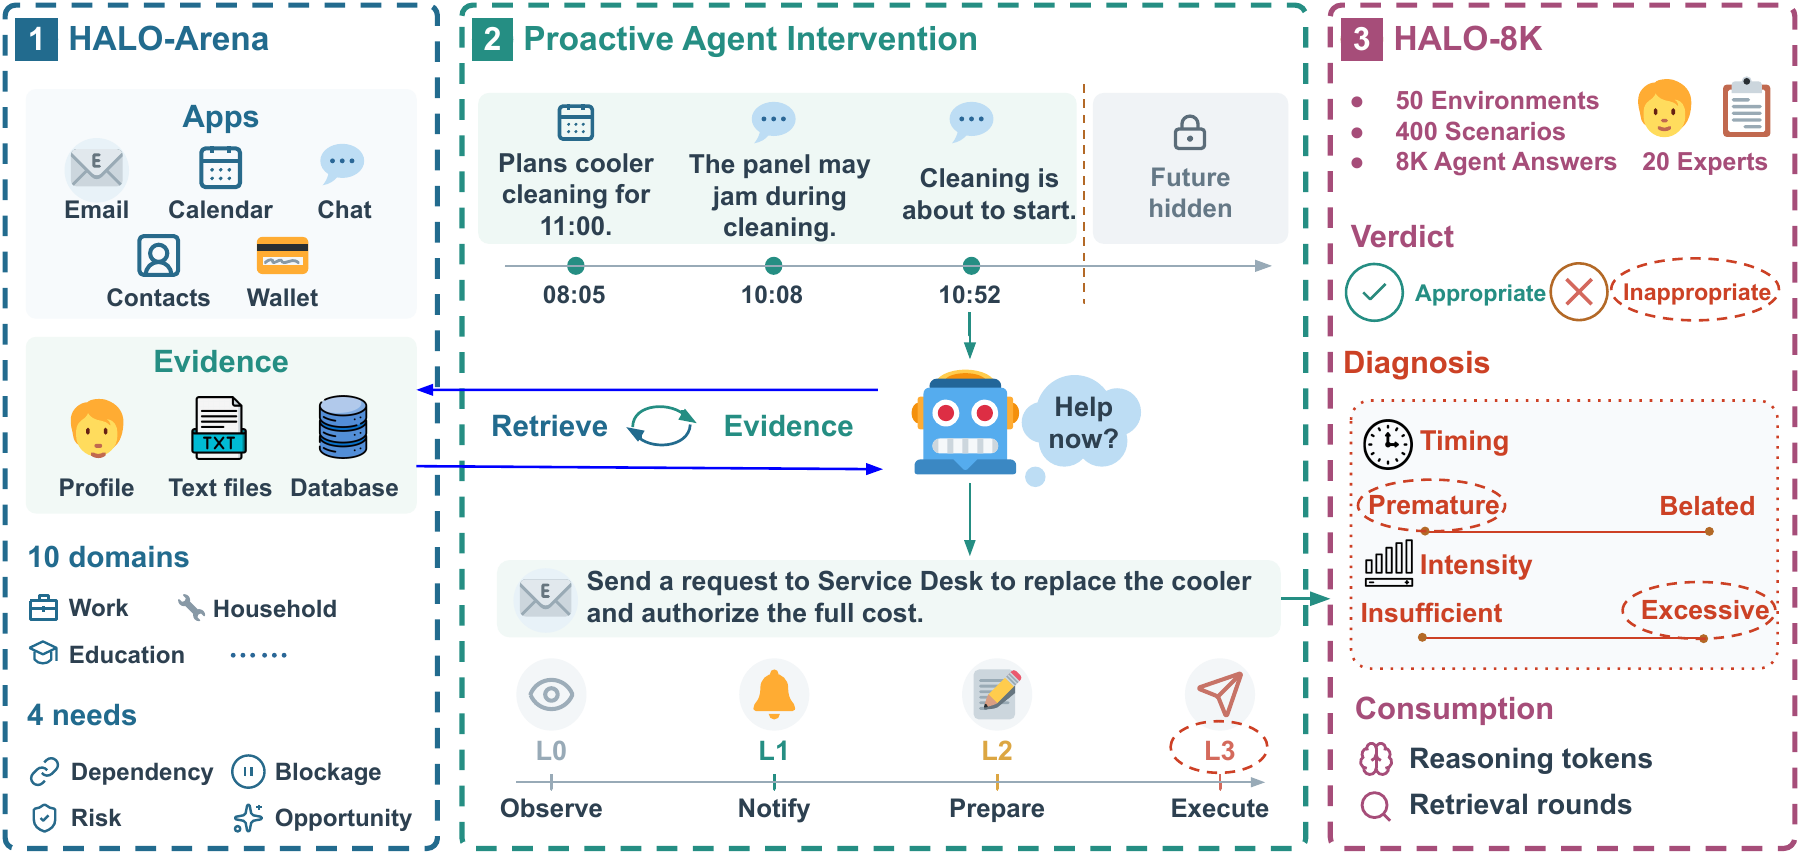
HALO: Human-Grounded Granular Evaluation of Proactive Agents
In collaboration with 2077AI
Wenqi Pei, Xinyu Wang, Jinrui Liu, Cynthia Zhuge, Jie Sheng, Zihan Wang, Tenghao Huang, Muhao Chen
Preprint 2026
We introduce HALO, a human-grounded framework for evaluating whether, when, and how far proactive agents should assist. HALO-Arena spans four proactive need types across ten everyday domains, while HALO-8K contains 8,000 responses from ten models annotated by twenty experts. Granular human judgments of timing, intensity, and acceptability reveal over-proactivity as the dominant observed failure mode.
HALO: Human-Grounded Granular Evaluation of Proactive Agents
In collaboration with 2077AI
Wenqi Pei, Xinyu Wang, Jinrui Liu, Cynthia Zhuge, Jie Sheng, Zihan Wang, Tenghao Huang, Muhao Chen
Preprint 2026
We introduce HALO, a human-grounded framework for evaluating whether, when, and how far proactive agents should assist. HALO-Arena spans four proactive need types across ten everyday domains, while HALO-8K contains 8,000 responses from ten models annotated by twenty experts. Granular human judgments of timing, intensity, and acceptability reveal over-proactivity as the dominant observed failure mode.
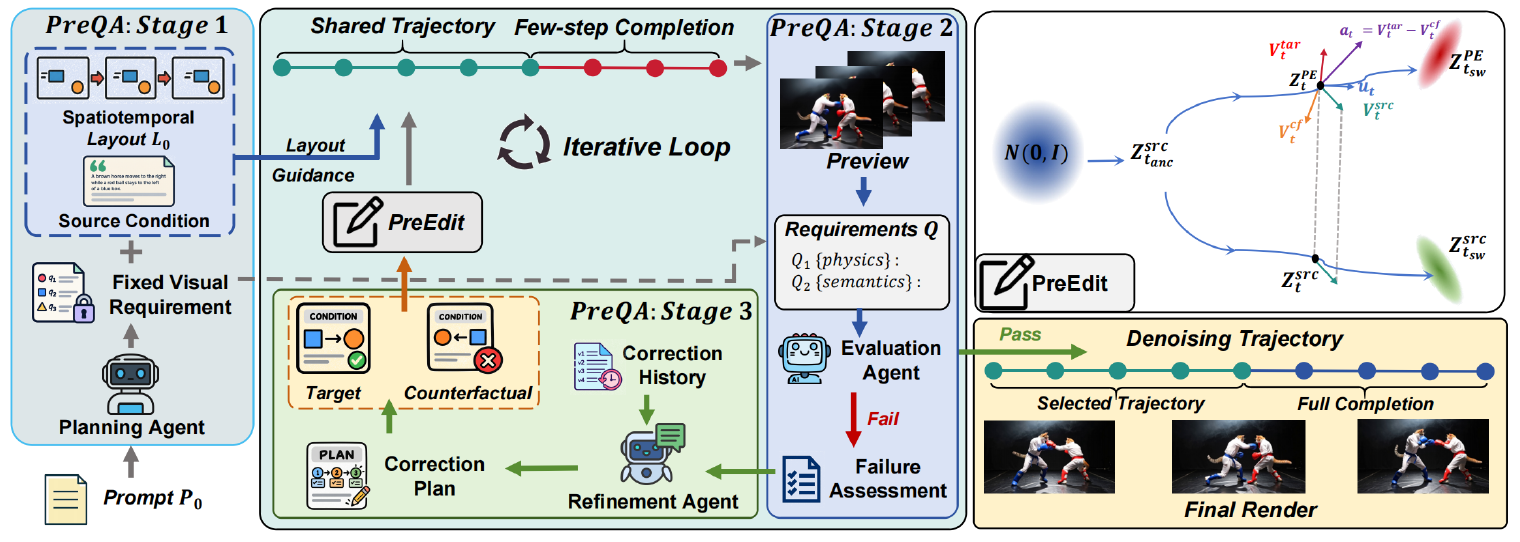
PreCoG: Preview-Edit for Efficient Video Correction in Generation-Time
Yilai Liu, Wenqi Pei, Zhifeng Lu, Shiyuan Zhang, Zongxi Liu, Hongyang Du
Preprint 2026
We introduce PreCoG, a framework that diagnoses semantic failures in low-cost video previews and corrects cached generation trajectories before final rendering. By combining PreQA assessment with PreEdit correction, it reduces redundant computation while preserving already correct content, achieving strong video quality and alignment at lower inference cost.
PreCoG: Preview-Edit for Efficient Video Correction in Generation-Time
Yilai Liu, Wenqi Pei, Zhifeng Lu, Shiyuan Zhang, Zongxi Liu, Hongyang Du
Preprint 2026
We introduce PreCoG, a framework that diagnoses semantic failures in low-cost video previews and corrects cached generation trajectories before final rendering. By combining PreQA assessment with PreEdit correction, it reduces redundant computation while preserving already correct content, achieving strong video quality and alignment at lower inference cost.
TempCloze: Can Video-LLMs Identify the Missing Middle?
Wenqi Pei*, Hengyuan Zhao*, Yilai Liu*, Jiahao Meng, Han Chen, Ziyu Wang, Hongyang Du (* equal contribution)
EMNLP Findings 2026
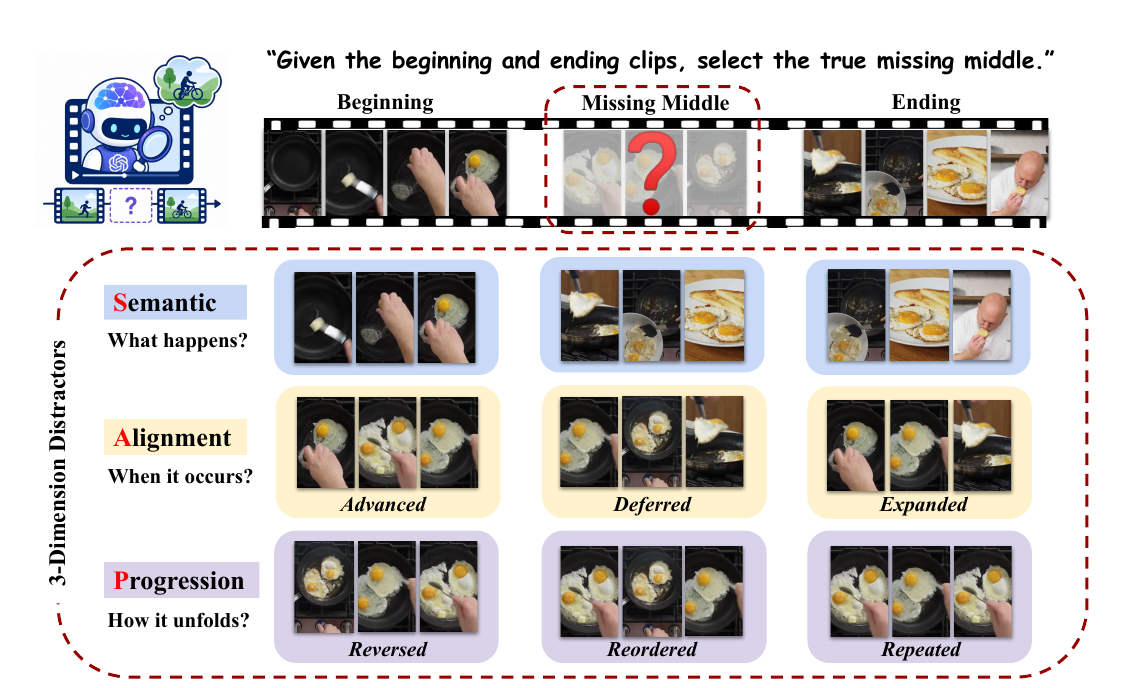
We introduce TempCloze, a video cloze benchmark for evaluating visual temporal reasoning in Video-LLMs by asking them to identify the true missing middle between beginning and ending clips. Across 1,521 videos and 31 Video-LLMs, TempCloze reveals temporal alignment as the primary bottleneck.
TempCloze: Can Video-LLMs Identify the Missing Middle?
Wenqi Pei*, Hengyuan Zhao*, Yilai Liu*, Jiahao Meng, Han Chen, Ziyu Wang, Hongyang Du (* equal contribution)
EMNLP Findings 2026
We introduce TempCloze, a video cloze benchmark for evaluating visual temporal reasoning in Video-LLMs by asking them to identify the true missing middle between beginning and ending clips. Across 1,521 videos and 31 Video-LLMs, TempCloze reveals temporal alignment as the primary bottleneck.
How to Make Tool-Using LLM Agents Efficient? A Survey
Yunuo Hu*, Ziyang Cheng*, Wenqi Pei*‡, Miaomiao Li, Boyan Li, Yizhang Zhu, Yupeng Xie, Han Chen, Shizheng Hou, Yuyu Luo, Hongyang Du (* equal contribution, ‡ project lead)
EACL Findings 2027
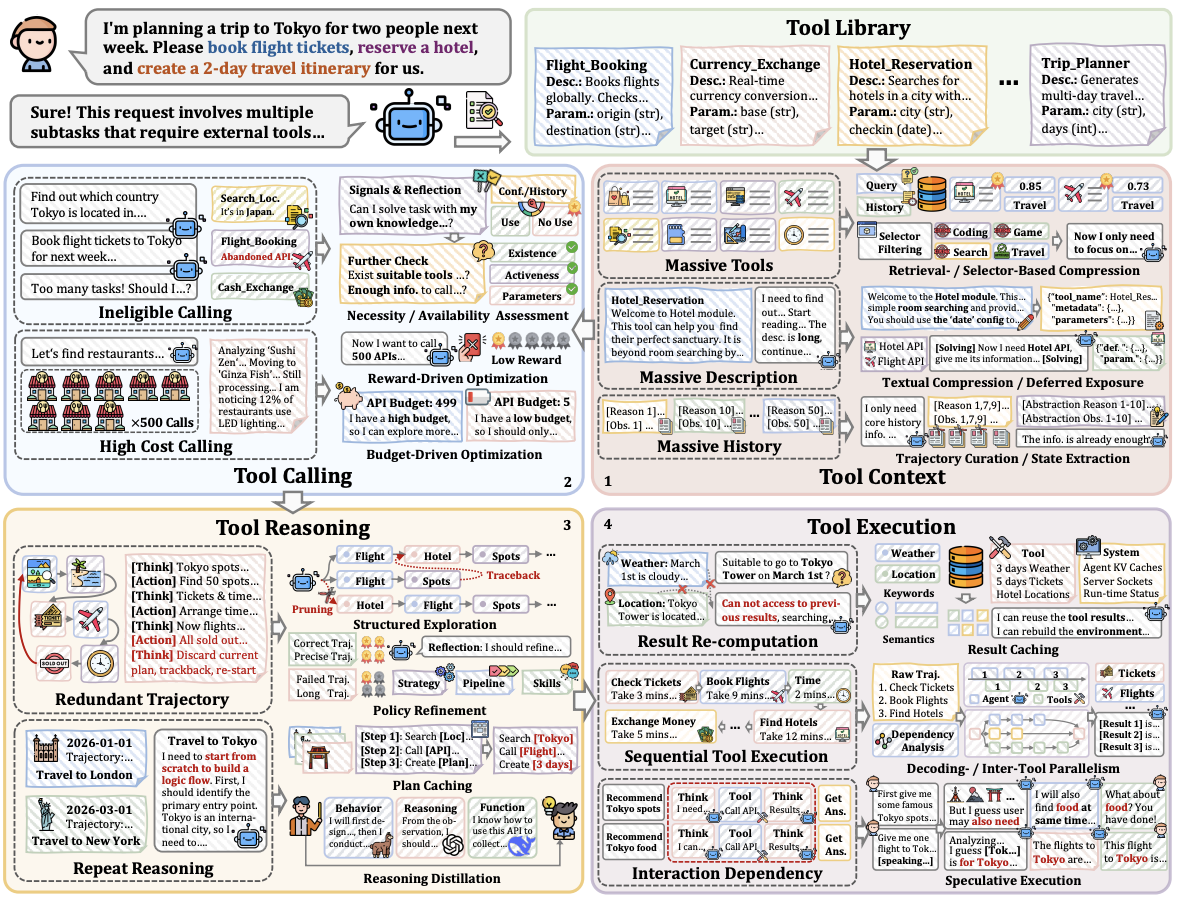
We present a systematic survey and unified taxonomy of efficient tool-using LLM agents, organizing techniques across tool context, calling, reasoning, and execution. We synthesize shared mechanisms, limitations, open challenges, and future directions for reducing resource use while preserving task performance.
How to Make Tool-Using LLM Agents Efficient? A Survey
Yunuo Hu*, Ziyang Cheng*, Wenqi Pei*‡, Miaomiao Li, Boyan Li, Yizhang Zhu, Yupeng Xie, Han Chen, Shizheng Hou, Yuyu Luo, Hongyang Du (* equal contribution, ‡ project lead)
EACL Findings 2027
We present a systematic survey and unified taxonomy of efficient tool-using LLM agents, organizing techniques across tool context, calling, reasoning, and execution. We synthesize shared mechanisms, limitations, open challenges, and future directions for reducing resource use while preserving task performance.
ROSE: An Intent-Centered Evaluation Metric for NL2SQL
Wenqi Pei*, Shizheng Hou*, Boyan Li*, Han Chen, Zhichao Shi, Yuyu Luo (* equal contribution)
ACL Main 2026
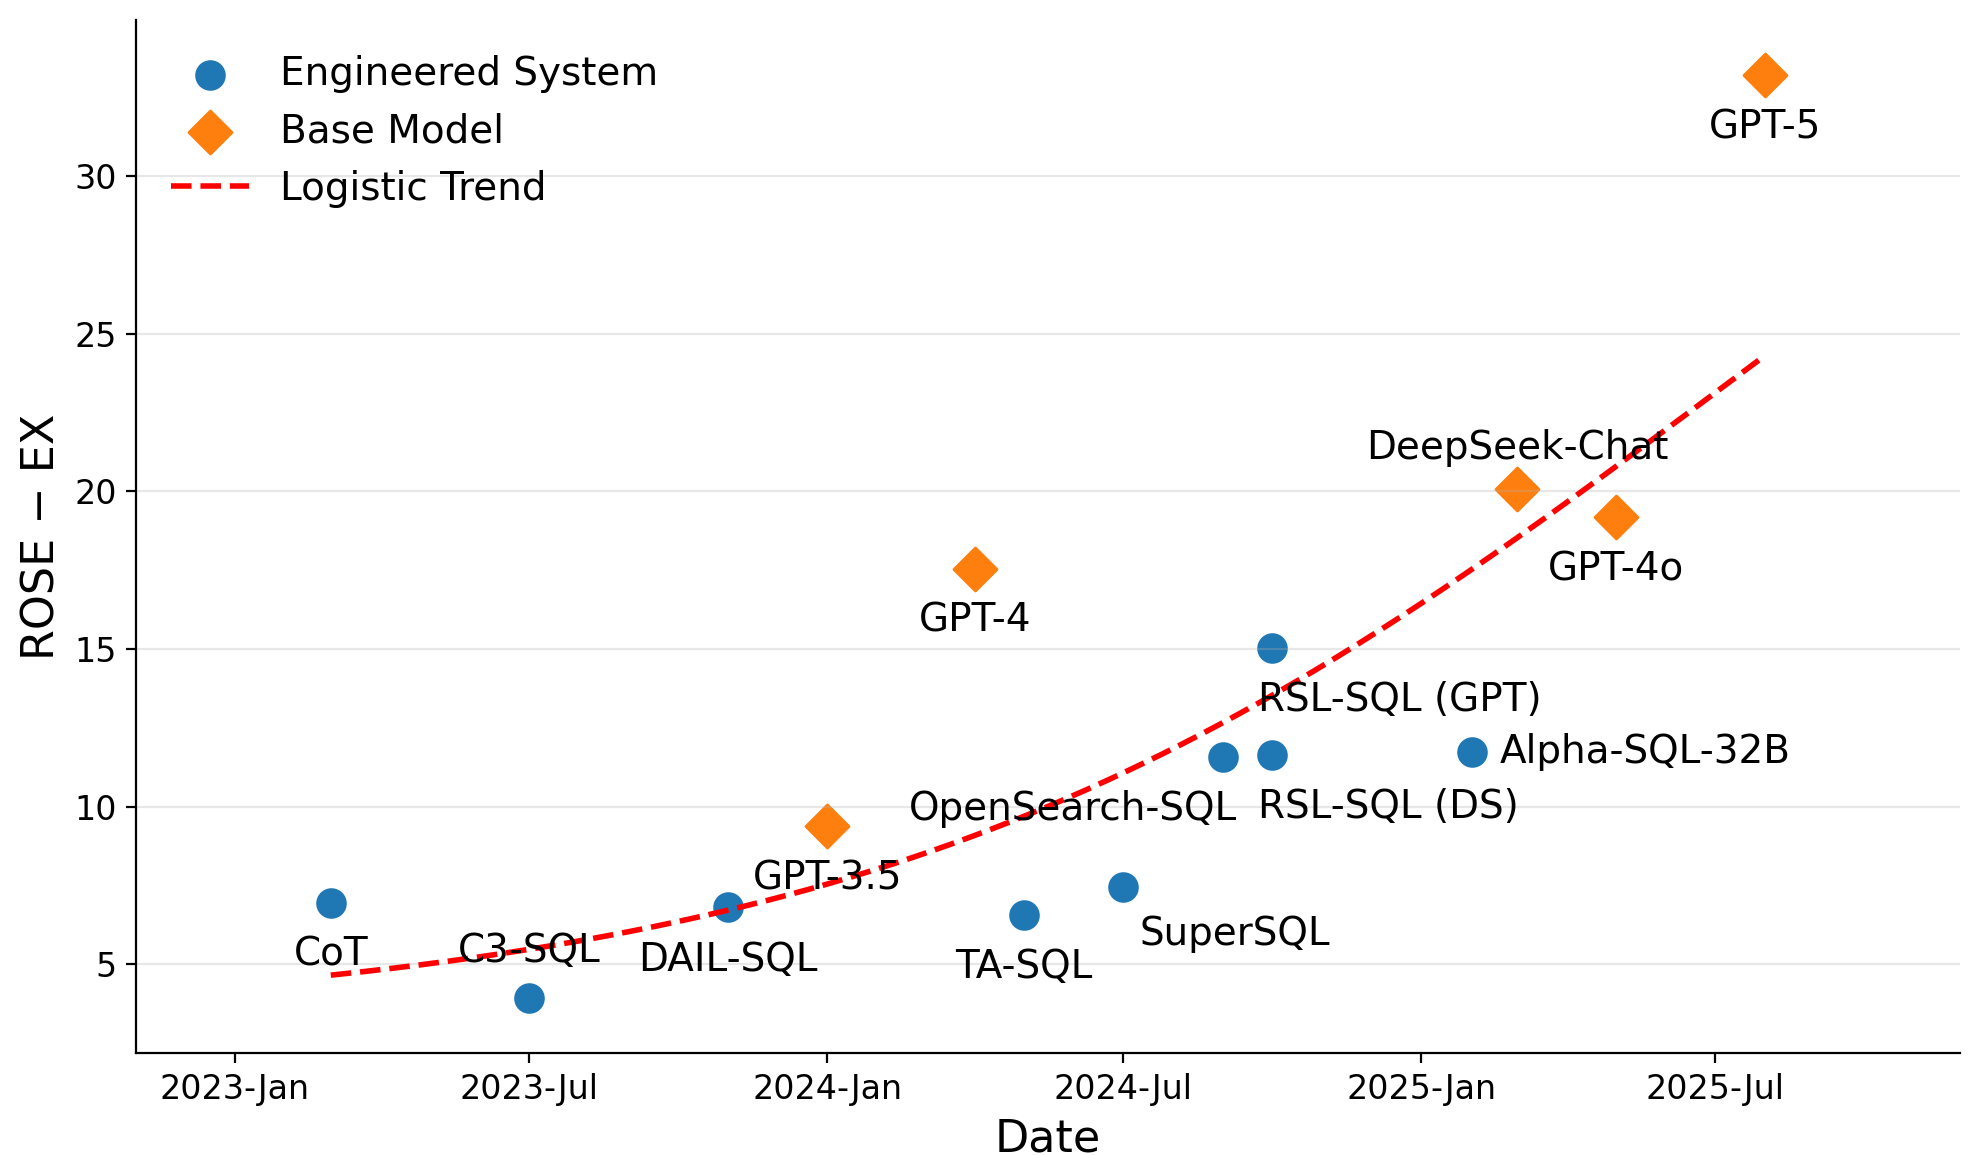
We introduce ROSE, an intent-centered evaluation metric for NL2SQL that uses an adversarial Prover-Refuter cascade to judge whether predicted SQL captures a user's intent. ROSE aligns more closely with expert assessments and supports a large-scale re-evaluation of 19 NL2SQL methods.
ROSE: An Intent-Centered Evaluation Metric for NL2SQL
Wenqi Pei*, Shizheng Hou*, Boyan Li*, Han Chen, Zhichao Shi, Yuyu Luo (* equal contribution)
ACL Main 2026
We introduce ROSE, an intent-centered evaluation metric for NL2SQL that uses an adversarial Prover-Refuter cascade to judge whether predicted SQL captures a user's intent. ROSE aligns more closely with expert assessments and supports a large-scale re-evaluation of 19 NL2SQL methods.

NL2SQLBench: A Modular Benchmarking Framework for LLM-Enabled NL2SQL Solutions
Shizheng Hou, Wenqi Pei, Nuo Chen, Quang-Trung Ta, Peng Lu, Beng Chin Ooi
VLDB 2026
We present NL2SQLBench, the first modular benchmarking framework for LLM-enabled NL2SQL approaches. We dissect NL2SQL systems into three modules: Schema Selection, Candidate Generation, and Query Revision. We review existing strategies and propose fine-grained metrics that systematically quantify module-level effectiveness and efficiency.
NL2SQLBench: A Modular Benchmarking Framework for LLM-Enabled NL2SQL Solutions
Shizheng Hou, Wenqi Pei, Nuo Chen, Quang-Trung Ta, Peng Lu, Beng Chin Ooi
VLDB 2026
We present NL2SQLBench, the first modular benchmarking framework for LLM-enabled NL2SQL approaches. We dissect NL2SQL systems into three modules: Schema Selection, Candidate Generation, and Query Revision. We review existing strategies and propose fine-grained metrics that systematically quantify module-level effectiveness and efficiency.

InterFeedback: Unveiling Interactive Intelligence of Large Multimodal Models with Human Feedback
Hengyuan Zhao*, Wenqi Pei*, Yifei Tao*, Haiyang Mei, Mike Zheng Shou (* equal contribution)
EMNLP Findings and Bi-Align @ ICLR (Oral) 2025
This work introduces InterFeedback, a novel approach to understanding and enhancing the interactive intelligence of large multimodal models through human feedback mechanisms. Our framework provides new insights into model behavior and interaction patterns.
InterFeedback: Unveiling Interactive Intelligence of Large Multimodal Models with Human Feedback
Hengyuan Zhao*, Wenqi Pei*, Yifei Tao*, Haiyang Mei, Mike Zheng Shou (* equal contribution)
EMNLP Findings and Bi-Align @ ICLR (Oral) 2025
This work introduces InterFeedback, a novel approach to understanding and enhancing the interactive intelligence of large multimodal models through human feedback mechanisms. Our framework provides new insights into model behavior and interaction patterns.

Feather-SQL: A Lightweight NL2SQL Framework with Dual-Model Collaboration Paradigm for Small Language Models
In collaboration with 4Paradigm
Wenqi Pei, Hailing Xu, Hengyuan Zhao, Shizheng Hou, Han Chen, Zining Zhang, Pingyi Luo, Bingsheng He
IJCNLP-AACL Findings and DL4C @ ICLR 2025
We present Feather-SQL, a novel framework for Natural Language to Structured Query Language (NL2SQL) that leverages dual-model collaboration paradigm specifically designed for small language models. Our approach achieves state-of-the-art (SOTA) results on the BIRD benchmark.
Feather-SQL: A Lightweight NL2SQL Framework with Dual-Model Collaboration Paradigm for Small Language Models
In collaboration with 4Paradigm
Wenqi Pei, Hailing Xu, Hengyuan Zhao, Shizheng Hou, Han Chen, Zining Zhang, Pingyi Luo, Bingsheng He
IJCNLP-AACL Findings and DL4C @ ICLR 2025
We present Feather-SQL, a novel framework for Natural Language to Structured Query Language (NL2SQL) that leverages dual-model collaboration paradigm specifically designed for small language models. Our approach achieves state-of-the-art (SOTA) results on the BIRD benchmark.