2026
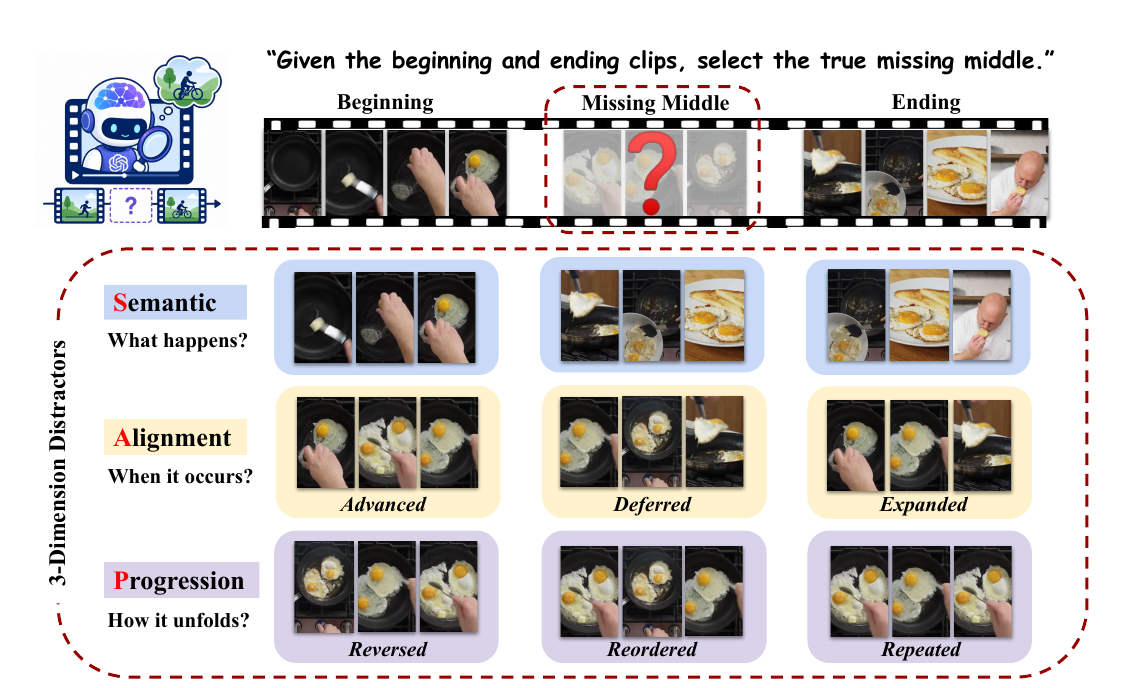
TempCloze: Can Video-LLMs Identify the Missing Middle?
Wenqi Pei*, Hengyuan Zhao*, Yilai Liu*, Jiahao Meng, Han Chen, Ziyu Wang, Hongyang Du (* equal contribution)
EMNLP Finding 2026
We introduce TempCloze, a video cloze benchmark for evaluating visual temporal reasoning in Video-LLMs by asking them to identify the true missing middle between beginning and ending clips. Across 1,521 videos and 31 Video-LLMs, TempCloze reveals temporal alignment as the primary bottleneck.
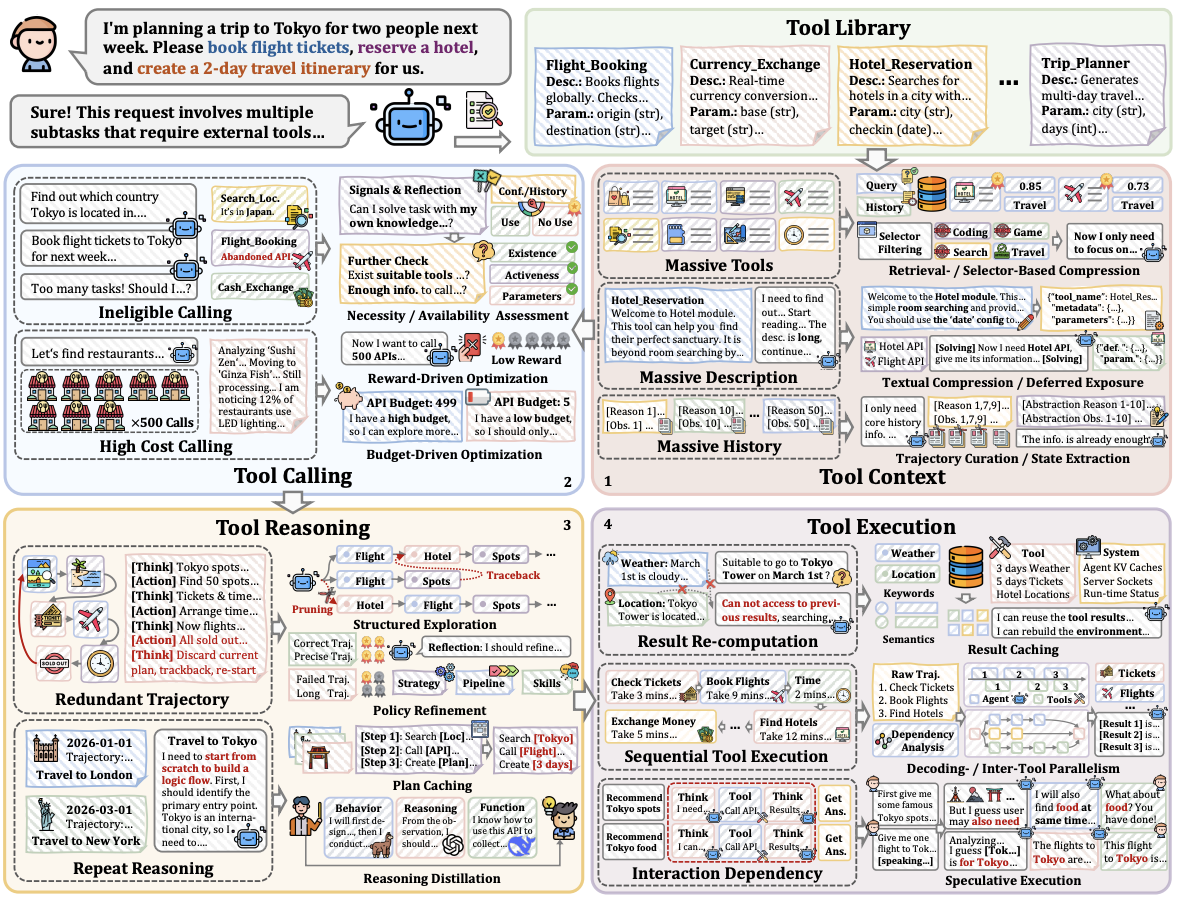
How to Make Tool-Using LLM Agents Efficient? A Survey
Yunuo Hu*, Ziyang Cheng*, Wenqi Pei*‡, Miaomiao Li, Boyan Li, Yizhang Zhu, Yupeng Xie, Han Chen, Shizheng Hou, Yuyu Luo, Hongyang Du (* equal contribution, ‡ project lead)
Preprint 2026
We present a systematic survey and unified taxonomy of efficient tool-using LLM agents, organizing techniques across tool context, calling, reasoning, and execution. We synthesize shared mechanisms, limitations, open challenges, and future directions for reducing resource use while preserving task performance.
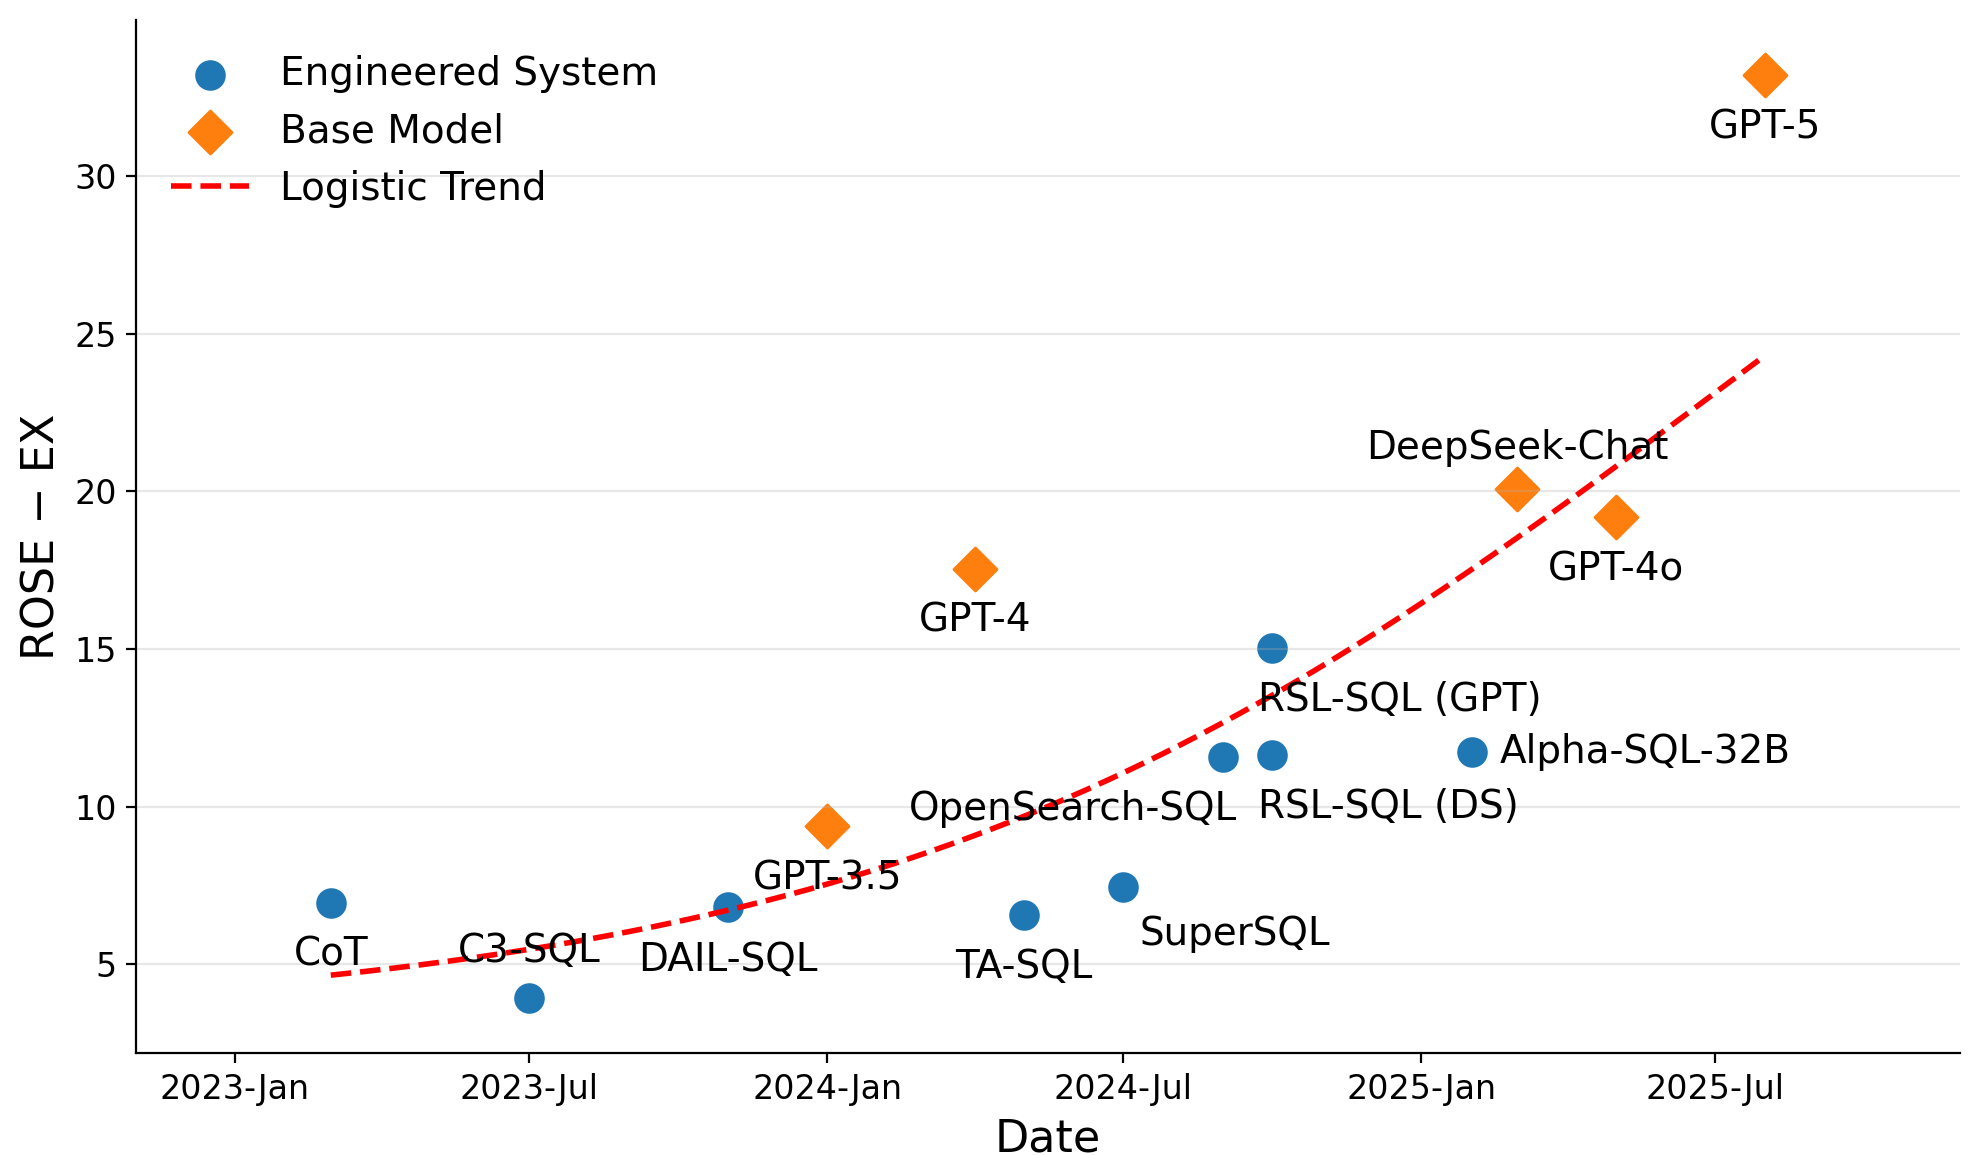
ROSE: An Intent-Centered Evaluation Metric for NL2SQL
Wenqi Pei*, Shizheng Hou*, Boyan Li*, Han Chen, Zhichao Shi, Yuyu Luo (* equal contribution)
ACL 2026
We introduce ROSE, an intent-centered evaluation metric for NL2SQL that uses an adversarial Prover-Refuter cascade to judge whether predicted SQL captures a user's intent. ROSE aligns more closely with expert assessments and supports a large-scale re-evaluation of 19 NL2SQL methods.
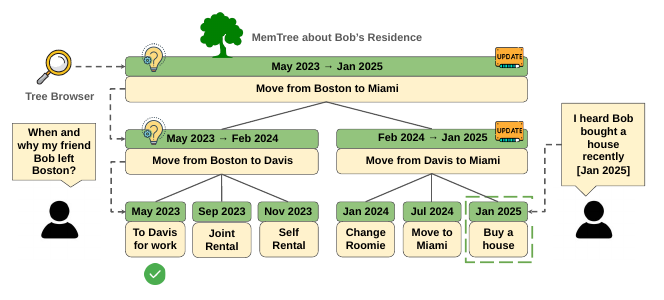
MemForest: An Efficient Agent Memory System with Hierarchical Temporal Indexing
Han Chen, Zining Zhang, Wenqi Pei, Bingsheng He, Ming Wu, Jason Zeng, Michael Heinrich, Wei Wu, Hongbao Zhang
Preprint 2026
We present MemForest, an efficient long-context agent memory system that combines parallel extraction with a hierarchical temporal index. Its localized update design reduces memory-freshness latency while retaining strong answer quality on LongMemEval-S and LoCoMo.
2025

NL2SQLBench: A Modular Benchmarking Framework for LLM-Enabled NL2SQL Solutions [Experiment, Analysis & Benchmark]
Shizheng Hou, Wenqi Pei, Nuo Chen, Quang-Trung Ta, Peng Lu, Beng Chin Ooi
VLDB 2026
We present NL2SQLBench, the first modular benchmarking framework for LLM-enabled NL2SQL approaches. We dissect NL2SQL systems into three modules: Schema Selection, Candidate Generation, and Query Revision. We review existing strategies and propose fine-grained metrics that systematically quantify module-level effectiveness and efficiency.

Self-Monitoring Large Language Models for Click-Through Rate Prediction
Huachi Zhou, Kaijing Yu, Qinggang Zhang, Hao Chen, Daochen Zha, Wenqi Pei, Anthony Kong, Xiao Huang
ACM TOIS 2025
We propose Feature-Instructed Large language model for Monitoring (FILM), which introduces a self-monitoring temperature and an compaction loss. FILM not only improves feature utilization in LLMs but also enhances predictions for tail items.

InterFeedback: Unveiling Interactive Intelligence of Large Multimodal Models with Human Feedback
Hengyuan Zhao*, Wenqi Pei*, Yifei Tao*, Haiyang Mei, Mike Zheng Shou (* equal contribution)
EMNLP Finding & ICLR Bi-Align (Oral) 2025
This work introduces InterFeedback, a novel approach to understanding and enhancing the interactive intelligence of large multimodal models through human feedback mechanisms. Our framework provides new insights into model behavior and interaction patterns.

Feather-SQL: A Lightweight NL2SQL Framework with Dual-Model Collaboration Paradigm for Small Language Models
Wenqi Pei, Hailing Xu, Hengyuan Zhao, Shizheng Hou, Han Chen, Zining Zhang, Pingyi Luo, Bingsheng He
IJCNLP-AACL Finding & ICLR DL4C 2025
We present Feather-SQL, a novel framework for Natural Language to Structured Query Language (NL2SQL) that leverages dual-model collaboration paradigm specifically designed for small language models. Our approach achieves state-of-the-art (SOTA) results on the BIRD benchmark.